Ever had a chatbot forget something you told it ten minutes ago?
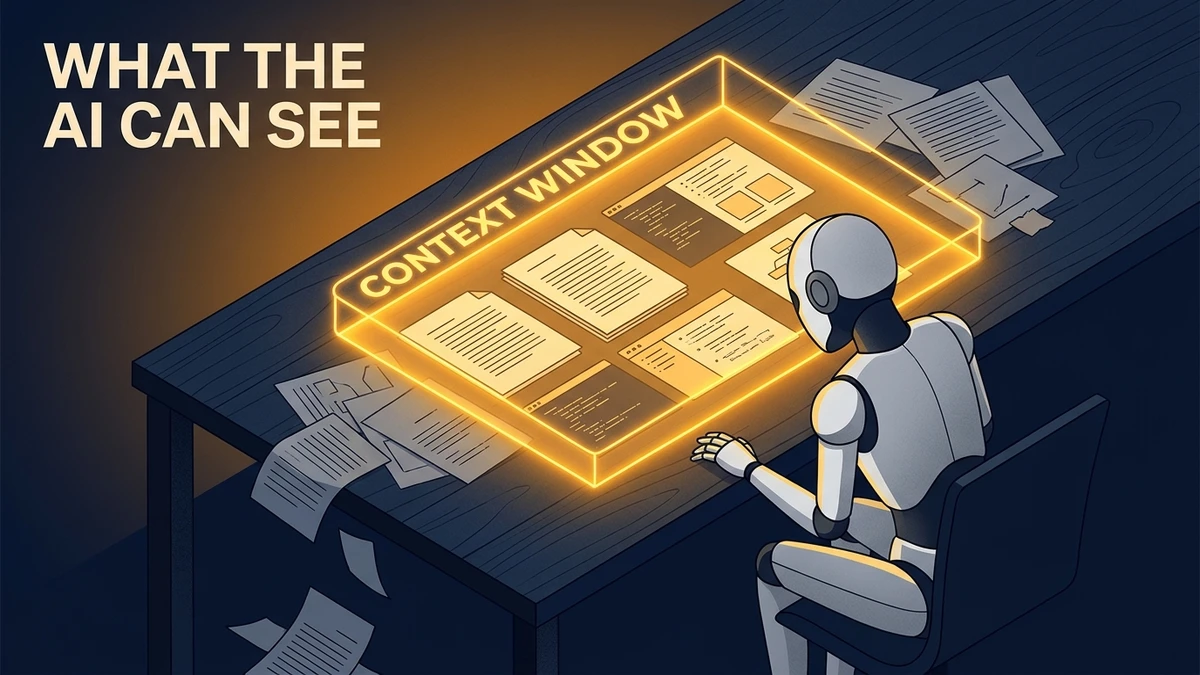
It probably was not being careless. It ran into its context window, the limit on how much text an AI model can hold in view at once. Everything inside the window is visible to the model. Anything outside it might as well not exist.
This guide explains what a context window is, how tokens work, how large windows are today, and the practical effects on cost, speed, and accuracy. It ends with ten ways to work cleanly within the limit.
The Short Answer
In one line: A context window is the model’s working desk. It holds the instructions, the conversation, any documents, and the answer being written, and it is measured in tokens.
The window covers input and output together. A model with a 128K window that receives 100K tokens of input has only about 28K left for its reply.
What Is a Token?
A token is a small chunk of text, often a short word or part of a word. A common rule of thumb is that one token is about three-quarters of an English word.
| Tokens | About this many words | About this much text |
|---|---|---|
| 1,000 | 750 | A long email |
| 100,000 | 75,000 | About 250 pages |
| 200,000 | 150,000 | About 550 pages |
The page figures follow DataHub’s benchmark guide. Code and text in many non-English languages often use more tokens per word, so your real capacity can be smaller—something worth factoring in alongside hardware capacity in our LLM VRAM calculator when running models locally.
What Fills the Window
- The system prompt. Hidden instructions that set the model’s behaviour.
- The chat history. Every earlier message, resent with each new request.
- Documents. Files you upload or text retrieved by a search tool.
- Tool results. Output from code runs, web pages, or external connectors such as Model Context Protocol (MCP) servers.
- Your question.
- The answer. The model’s reply counts against the same budget.
This is why long conversations hit the limit sooner than people expect. The whole history rides along every time.
A Worked Example
Using the page-to-token rule of thumb above, here is how a typical document Q&A turn adds up:
| Item | Approximate tokens |
|---|---|
| 40-page report | 16,000 |
| Earlier chat messages | 6,000 |
| System prompt | 1,000 |
| Your question | 200 |
| Reserved for the answer | 2,000 |
| Total | about 25,200 |
That fits easily inside a 128K window. Size is not the problem here. Where the key fact sits in the report may matter more.
How Big Are Context Windows?
| Size | Typical examples | Roughly holds |
|---|---|---|
| 8K to 32K | Older and small models | A short report |
| About 128K | Many mainstream models | A small codebase or long transcript |
| About 200K | Claude family, historically | A large document |
| 1M and above | Gemini and other long-context models | Several books |
| 10M | Meta’s Llama 4 Scout, with open weights | The largest published figure |
Verify before you build: Guides disagree on exact numbers, and vendors keep changing them. Treat the table as a rough map and confirm each model’s window and output cap on the provider’s own page.
Output limits are much smaller than input windows. One 2025 guide lists output caps of roughly 8,000 to 65,000 tokens even for models that accept far more input. On self-hosted hardware, expanding context length also inflates the dynamic KV cache rapidly—a memory constraint explored in our LLM quantization and memory sizing guide.
Why Bigger Is Not Always Better
- Cost. You pay for every token you send, so stuffing in a whole library gets expensive.
- Speed. Longer inputs generally take longer to process.
- Accuracy. Recall can weaken as input grows, which brings us to the next two problems.
- Advertised vs effective. One 2025 study cited by Atlan found effective context can fall far below the advertised limit on complex tasks.
Lost in the Middle
A 2023 study from Stanford and UC Berkeley, “Lost in the Middle,” found that models use information best at the start and end of a long prompt, and worst in the middle. Accuracy follows a U-shaped curve.
| Where the fact sits | How well it is used | Why |
|---|---|---|
| Start | Strong | Models attend heavily to the opening |
| Middle | Weaker | Attention is spread thin |
| End | Strong | Recent text has outsized influence |
Guides citing the research put the drop for middle-of-context facts at roughly 20% to 40%, depending on the study. A bigger window does not remove the problem. It gives you a longer middle to lose things in.
Context Rot
Chroma’s 2025 “Context Rot” report tested 18 models and found performance becomes less reliable as input length grows, even on simple tasks. Anthropic’s documentation also notes that accuracy and recall degrade as token count grows.
What Happens When You Hit the Limit
| What you see | Likely cause |
|---|---|
| An error saying the input is too long | Your prompt plus the reserved output exceeds the window |
| The model ignores early instructions | Old messages were trimmed, or the instructions are lost in the middle |
| A reply cut off mid-sentence | The output cap was reached |
| Wrong details from a long document | The needed fact sat in a weak part of the context |
Behavior depends on the app. Some tools trim the oldest messages, some summarize them, and some stop with an error.
Practical Effects by Use Case
| Use | What the window changes | Tip |
|---|---|---|
| Chatting | Long sessions drift or forget | Start a fresh chat for each new task |
| Document Q&A | Large files may not fit or may be skimmed | Ask for exact quotes to check answers |
| Coding agents | Each step adds tokens. A 50-step workflow using 20,000 tokens a call spends 1,000,000 tokens in total | Keep tasks small and summarize progress across AI coding tools |
| Support bots | Long histories raise cost per reply | Trim history and keep a short summary |
| Content work | Huge style guides crowd out the task | Keep instructions short and specific |
10 Ways to Work Within the Window
| # | Tip | Why it helps |
|---|---|---|
| 1 | Put key instructions at the start and end | Those positions are used best |
| 2 | Remove irrelevant text | Fewer tokens means less cost and less noise |
| 3 | Use retrieval for large collections | Search first, then send only the relevant passages |
| 4 | Summarize old conversation | Keeps the gist without the length |
| 5 | Start a new chat for a new task | Gives the model a clean slate |
| 6 | Ask for quotes and sources | Makes missed details easier to spot |
| 7 | Split long documents into parts | Keeps each request in the strong zone |
| 8 | Reuse a stable prompt prefix | Some providers discount repeated prefixes. Check yours |
| 9 | Set a sensible output length | Leaves room in the window and avoids waste |
| 10 | Test on your own data | Advertised limits are not effective limits |
Context Window vs Memory vs RAG
| Term | What it is | How it differs |
|---|---|---|
| Context window | Text the model can see right now | Temporary and limited in size |
| Memory features | Saved notes an app can add to future chats | Stored outside the model and re-inserted into the window |
| RAG | Searching a knowledge base and sending relevant pieces | A RAG pipeline architecture fits big collections into a small window |
Memory features and RAG both work by putting the right text into the window at the right moment. They do not enlarge the window.
Related Reading & Deeper Context
- What Is an AI Agent? A Beginner Guide — how autonomous agents manage state, memory, and multi-step tool calls across context limits.
- RAG Pipeline Explained: Components and Workflow — how retrieval narrows huge document collections to fit the active context window.
Frequently Asked Questions
What is a context window in AI?
It is the maximum amount of text, measured in tokens, that a model can process in a single request, including your prompt, history, documents, and the answer.
What is a token in an LLM?
A token is a small chunk of text, often part of a word. As a rule of thumb, one token is about three-quarters of an English word.
How many words is 100,000 tokens?
About 75,000 words, or roughly 250 pages of text.
What is the largest context window?
Meta’s Llama 4 Scout advertises 10 million tokens with open weights, the largest published figure across major model releases. Check current vendor specifications, since published limits change often.
What does “lost in the middle” mean?
It means models use information at the start and end of a long prompt better than information in the middle, which makes accuracy follow a U-shaped curve.
What is context rot?
Context rot is the decline in accuracy and recall as input length grows, even on simple tasks.
Is a bigger context window always better?
No. Larger windows cost more, can be slower, and still suffer from weaker recall in the middle. Use only as much context as the task needs.